A cluster should fit the workload.
Yours is specified, not selected. Accelerators, interconnect, storage, cooling, site: you select what matters to you, and we engineer to you.
Built to your spec, not our stock.
The accelerator generation, fabric, and storage profile your jobs actually need.
You choose where it runs.
Region and facility selected against your latency and data-residency requirements.
The specifications, up front.
You set the requirements. Our team co-designs the cluster around them, so everyone is working from the same numbers.
| Platform | Workload | Regions |
|---|---|---|
| Vera Rubin | Frontier training · Agentic inference | US · Europe · APAC |
| GB300 | Large-model training · Reasoning | NA · Europe · APAC |
| B300 | Training · Fine-tuning · Serving | NA · Europe · APAC |
Single-tenant. Take-or-pay. 3-to-5-year terms with pricing, service levels, and location specified by you.
Three questions, answered before you ask.
Price
The number you agree to is the number you pay.
Fixed monthly cost across a 36- or 60-month term. Zero CapEx, zero hidden fees, zero egress fees.
Experience
You inherit the experience instead of paying to learn it.
Axe Compute has designed, financed, built, and run dedicated clusters at production scale. That practice comes with the contract.
Availability
Engineered to your workload, not a fixed box.
Cluster scale set at co-design, sited in the region you require, with a midterm GPU upgrade available.
The foundation of every build.
Choice
Blackwell, Grace Blackwell, or Vera Rubin, configured to the workload and sited where you need it.
Expertise
Compute, fabric, storage, power, and cooling, co-designed by the engineers who will run it.
Execution
A committed date, engineered from the build plan. A 99.93% uptime SLA with service credits. 24/7 operations with on-site staff.
Global Reach
Capacity across multiple regions, with data residency handled at design time.
What Axe Compute does, end to end.
-
01Architect the solution
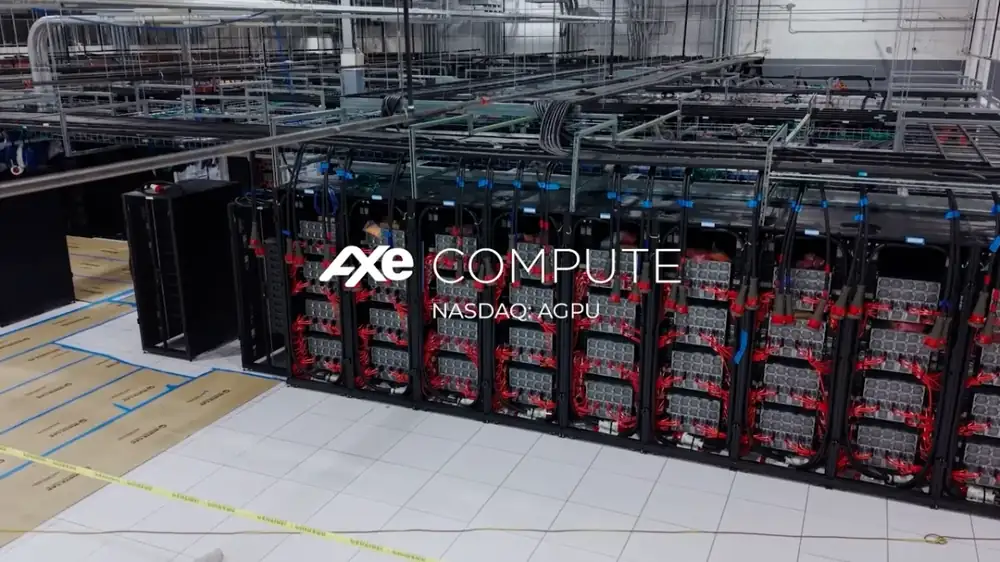
GPU selection, supporting infrastructure, networking, power, and space. A full AI factory design, including ancillary services.
-
02Finance and procure hardware
B200, B300, GB300, Vera Rubin, and more. Axe Compute funds and sources the build. You bring zero CapEx.
-
03Secure space and power
Data center space with dedicated power and N+1 redundancy, matched to your data sovereignty and performance requirements.
-
04Build, deliver, operate, support
Enterprise-grade SLAs on NVIDIA reference architecture. The cluster is fully tested to your acceptance criteria, then supported 24/7.
-
05Include the upgrade path
Move to the latest GPU architecture during the contract term, where your agreement provides for it. No lock-in on yesterday’s hardware.
-
06We own the hardware
Equipment sits on Axe Compute’s balance sheet as a hard asset, redeployable after the term. You carry no residual risk.
A partner through the full cycle.
AI runs in cycles: model generations, hardware generations, buildouts measured in years and megawatts. Winning through them takes a partner who stays: from contract and financing through deployment, daily operation, and the next hardware generation. One counterparty for the capital, the build, and the running of it.
You build the business. We build what it runs on.
Tell us what you need, and Axe Compute comes back with a concrete plan and a committed date.